Warehouse Exception Management: How to Stop Small Problems From Becoming Shipping Delays
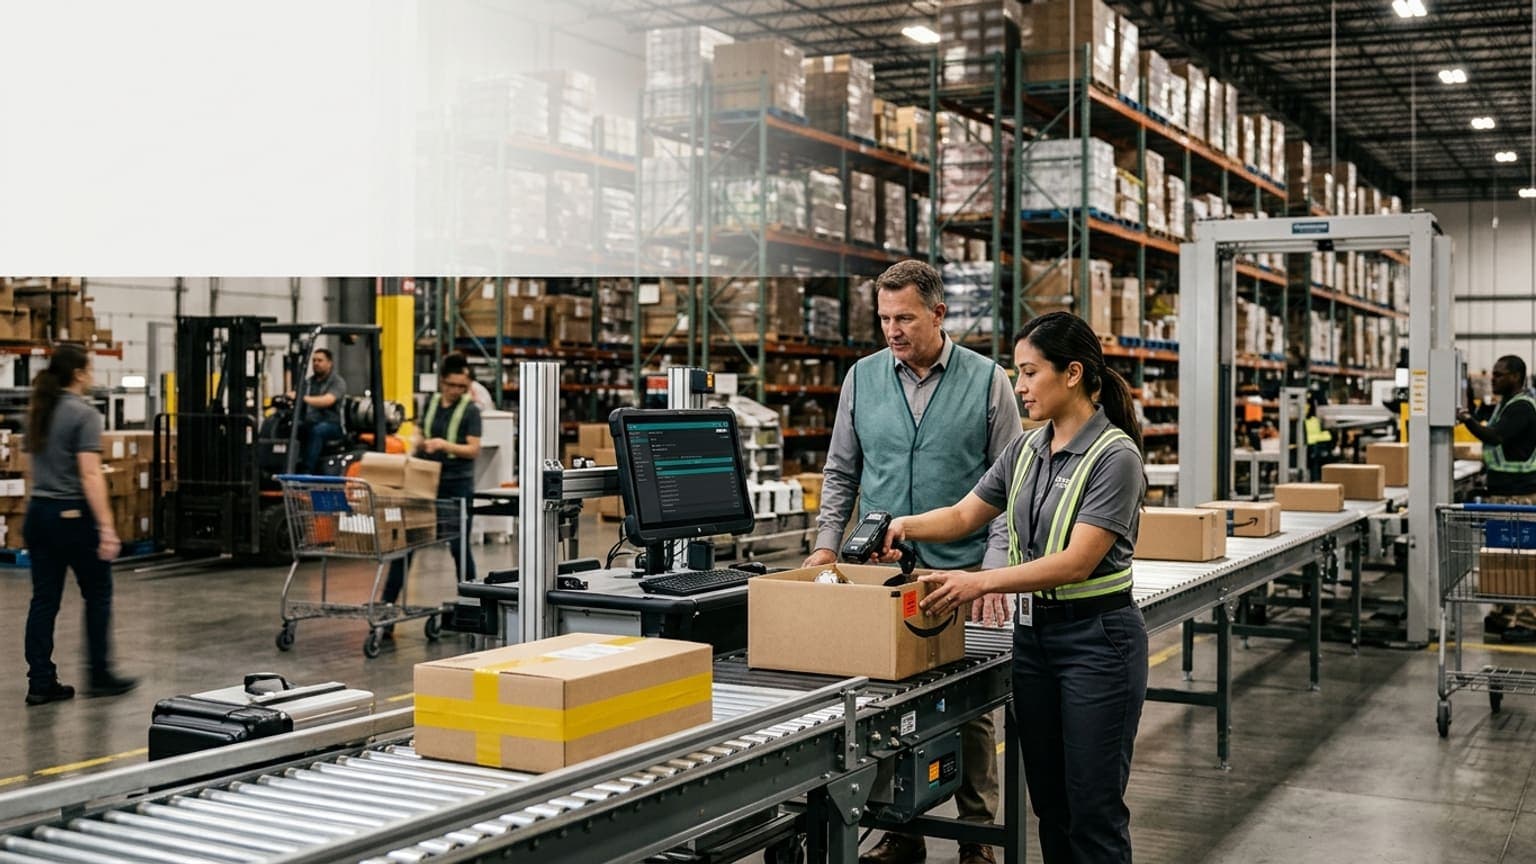
Warehouse exception management is the discipline that keeps small operational problems from turning into missed cutoffs, billing disputes, inventory errors, and customer-visible failures.
Most warehouses already have exceptions. The problem is that many of them are managed informally: a tote sits beside a pack bench, a damaged carton waits near receiving, a supervisor gets a message in chat, or an order is held because nobody knows whether inventory, transportation, customer service, or quality owns the next step.
That may work for a few issues per shift. It breaks when volume rises, labor changes, customers add requirements, or automation exposes more defects than the team can triage manually.
For warehouse buyers and operators, the goal is not to eliminate every exception. The goal is to make exceptions visible, owned, timed, and measurable before they block flow.
Define what counts as a warehouse exception
An exception is not simply "something unusual." It is an event that requires a controlled decision before work can continue.
Examples include:
- receiving a carton with visible damage, missing documents, or an unexpected SKU
- finding an item that does not match the purchase order, ASN, order, lot, serial, or license plate
- picking product from a location that shows a quantity mismatch
- packing an order where the item will not fit the recommended carton
- capturing weight or dimensions that do not match the expected package profile
- printing a carrier label that fails rating, address validation, or service-level rules
- releasing a pallet or shipment with missing photos, documents, compliance labels, or route data
- discovering a return with unclear condition, missing accessories, or mismatched customer information
The practical test is simple:
If an operator cannot safely continue without a decision, record, correction, or approval, it is an exception.
That definition matters because vague exception handling creates vague ownership. One team thinks the issue is inventory. Another thinks it is transportation. Customer service waits for status. The order ages while everyone assumes someone else is handling it.
Use reason codes that lead to action
Reason codes should do more than describe a problem. They should point to the next action.
Weak reason codes look like this:
- issue
- hold
- bad scan
- damaged
- mismatch
- other
They are easy to select, but they do not help supervisors clear work or fix root causes.
Stronger reason codes separate the operational cause:
- PO quantity mismatch
- ASN item not found
- barcode unreadable
- item master data missing
- lot or serial rule failed
- visible product damage
- carton damage only
- missing customer document
- carton recommendation rejected
- package weight variance
- package dimensions outside tolerance
- carrier label API failure
- address validation failure
- retailer routing guide issue
- supervisor approval required
Each code should answer four questions:
- Can work continue? Block, allow with approval, or allow with note.
- Who owns the next step? Receiving, inventory control, packing, quality, transportation, customer service, IT, or a supervisor.
- What evidence is required? Photo, rescan, reweigh, dimensions, document upload, operator note, or system error.
- What system must update? WMS, TMS, ERP, carrier platform, customer portal, billing system, or reporting queue.
This keeps the exception queue operational. A supervisor should be able to open the queue and understand what is blocked, why it is blocked, who owns it, and what action would release it.
Assign ownership before the queue grows
The most expensive exceptions are often not the hardest ones. They are the ones that sit too long.
A damaged inbound carton may need photos and supplier disposition. A parcel weight variance may need repack, reweigh, or service-level change. A missing serial number may need inventory control. A label failure may need transportation or IT. Each issue is manageable if the right team sees it quickly.
Build ownership rules before launch:
- one primary owner for each exception type
- one backup owner for each shift or site
- response targets by priority
- escalation rules when an exception approaches cutoff
- release criteria that say when work can continue
- override permissions for supervisors
- reporting that shows aged exceptions by owner
Avoid shared queues where everyone can see the work but nobody is accountable for it. Visibility without ownership only makes delays easier to observe.
For outbound operations, connect exception ownership to the release point. If a problem can block a truck, route, wave, or parcel manifest, it should be visible before dock release. The same logic applies to workflows described in the warehouse dock door release workflow and warehouse pack station automation requirements.
Capture evidence while the problem is still visible
Warehouse exceptions decay over time.
Damage gets separated from packaging. Labels are replaced. Pallets are rebuilt. Cartons are opened. Operators change shifts. The system status changes. By the time finance, customer service, or a carrier asks what happened, the original evidence may be gone.
Useful exception evidence can include:
- order, PO, shipment, carton, pallet, tote, license plate, SKU, lot, serial, customer, and carrier identifiers
- site, dock, aisle, station, lane, door, or work area
- operator, device, workflow step, and timestamp
- photos of product, packaging, labels, pallet condition, seal, or damage
- weight and dimensions when freight profile, billing, claims, or service level is affected
- expected value versus actual value
- system response, API error, printer error, scanner failure, or integration status
- action taken and release approval
Do not ask operators to write essays. Capture structured evidence at the point of work. A few controlled fields, images, and timestamps are more useful than a long note typed after the rush.
This is where automation can pay off. Scanners, cameras, scales, dimensioning systems, and workflow software should create an exception record that is tied to the physical item and the system transaction. The record should stay useful after the freight leaves the area.
Protect cutoff time with aging and priority rules
An exception is not equally urgent all day.
A B2B order that misses a retailer routing window can create chargebacks. A parcel held before carrier pickup can miss promised delivery. A damaged inbound item may block replenishment for a wave later in the shift. A label failure at 10 a.m. may be routine; the same failure 20 minutes before pickup may need escalation.
Use rules that reflect operational time pressure:
- high-priority customers, channels, routes, or orders
- carrier pickup and dock appointment times
- retailer compliance windows
- wave release and pack completion targets
- temperature, hazmat, expiration, lot, or serial constraints
- labor handoff between shifts
- aged exception thresholds such as 30, 60, 120, or 240 minutes
A strong queue does not just list exceptions. It shows which issues threaten flow now.
That may mean color, priority, sorting, alerts, or escalation. More important, it means clear release criteria. The team should know whether an exception needs a correction, a supervisor approval, a customer decision, a carrier response, or a controlled bypass before work can continue.
Measure exceptions as a process signal
Exception management should improve the warehouse, not become a permanent workaround.
Track KPIs that show both control and root cause:
- exception rate by workflow, site, shift, customer, carrier, SKU family, or operator group
- first-response time and total aging time
- exceptions cleared before cutoff
- exceptions released with supervisor override
- repeat reason codes
- rework hours tied to each exception type
- chargebacks, claims, carrier adjustments, or customer complaints linked to exceptions
- integration failures by system and message type
- percentage of exception records with required evidence
Read these numbers carefully. A rising exception rate after launch may not be bad if the warehouse is finally seeing issues that were previously hidden. The important question is whether aged exceptions, repeated root causes, and downstream failures are falling.
The best exception program eventually reduces noise. Better item data lowers scan mismatches. Better cartonization reduces pack exceptions. Better receiving inspection improves claims. Better dimension and weight records reduce carrier billing disputes. Better integration monitoring prevents silent failures.
Keep exceptions close to the physical workflow
Warehouse exception management works best when it lives near the work, not in a detached spreadsheet after the fact.
The operator should not need to leave the station, message three people, or invent a workaround. The workflow should identify the issue, collect the evidence, assign the owner, set the priority, and show whether the item can move.
That is especially important when automation is introduced. Faster conveyors, scanners, pack benches, dimensioning systems, and dock workflows can increase throughput, but they also expose more edge cases. If exception handling is not designed, automation simply moves uncertainty faster.
Sizelabs helps warehouse teams capture dimensions, weight, images, identifiers, timestamps, station context, operator context, exception status, and integration-ready records across receiving, returns, packing, pallet, freight, and outbound workflows. If exceptions are where your operation loses time, start by making the next decision visible before the work leaves the control point.